An AI voice detector estimates whether speech was machine-generated. On the in-the-wild Deepfake-Eval-2024 benchmark, the best commercial audio detector hit 0.89 accuracy and 0.93 AUC, while open-source models lost an average of 48% of their AUC.
What is an AI voice detector?
Definition: An AI voice detector is a classifier that analyzes a speech recording and returns a probability that the voice was synthesized or cloned by a machine rather than spoken live by a person.
The input is audio. The output is a number — usually between 0 and 1, sometimes shown as a percentage — attached to a label such as "likely synthetic" or "likely human." That number is an estimate, not a finding of fact.
Detectors learn from paired corpora. One side holds genuine recordings; the other holds output from text-to-speech engines, voice-conversion systems and cloning tools. The model absorbs the statistical fingerprints that separate the two groups: spectral artifacts, unnaturally regular breathing, phase behavior no human larynx produces.
One adjacent concept gets confused with detection constantly. Speaker verification asks "is this Maria?" and matches a voice against an enrolled profile. An AI voice detector asks a different question — "did any human body produce this sound?" — and a good clone can pass verification while failing detection, or the reverse.
That distinction matters for your workflow. If your concern is an unauthorized clone of a dubbing talent, verification tells you the voice resembles her; detection tells you whether the waveform looks machine-made. You usually need both signals, read together.
How an AI voice detector works: three stages from audio file to verdict
Stage 1 — Preprocessing and feature extraction
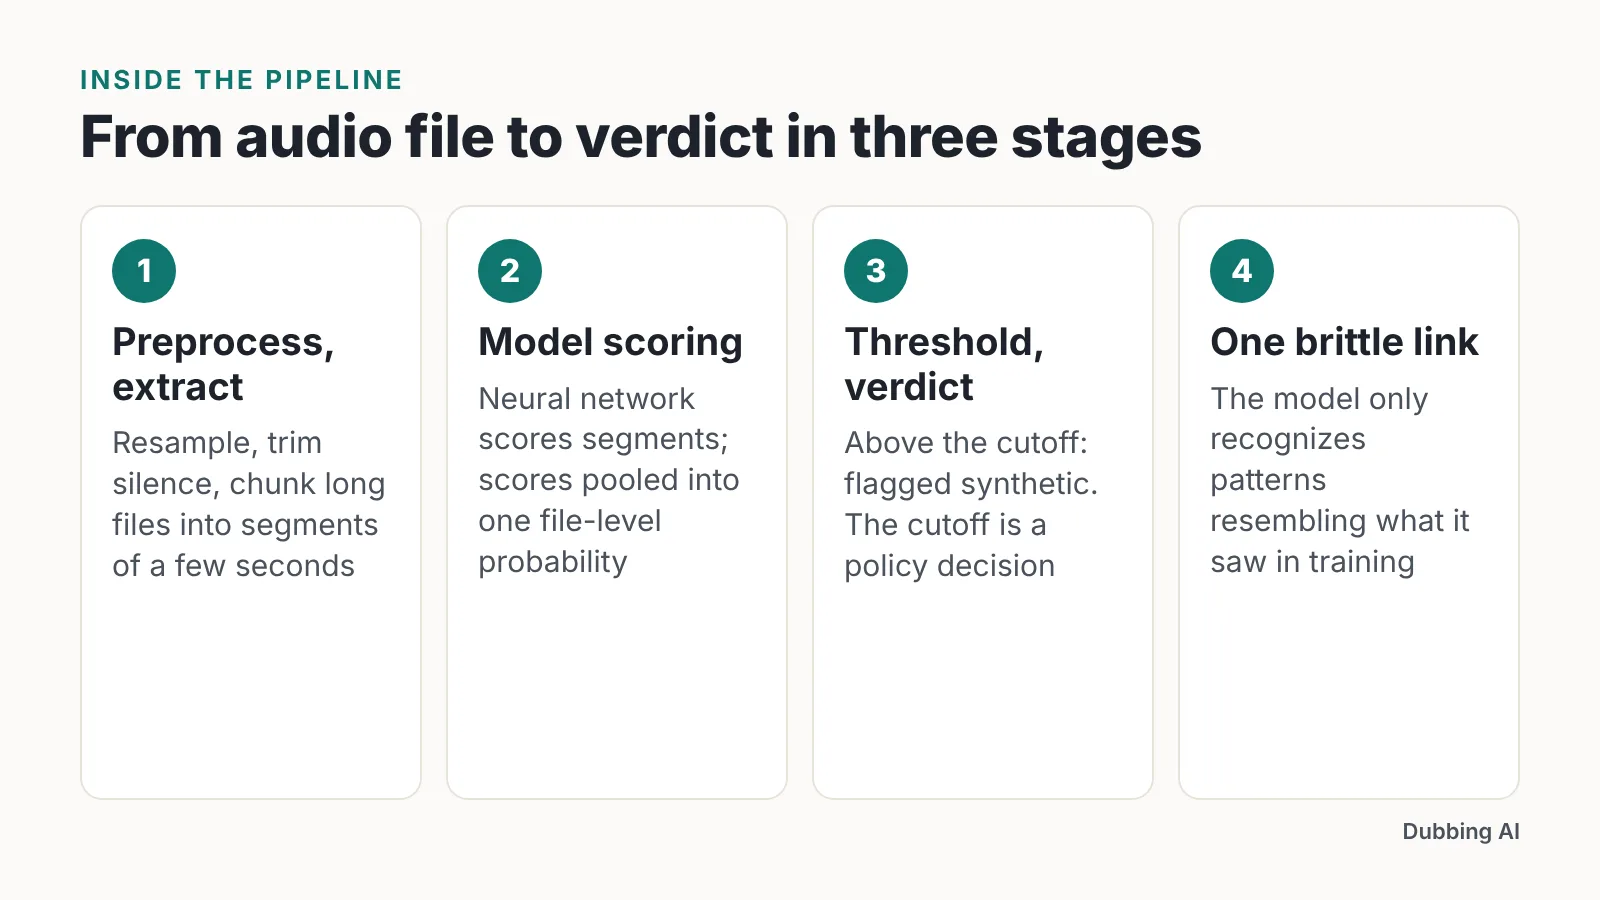
The file is resampled to a fixed rate, split into short frames, and converted into a representation the model can read: mel-spectrograms, raw waveform windows, or embeddings from a self-supervised speech model. Silence is often trimmed. Long files get chunked into segments of a few seconds each.
Stage 2 — Model scoring
A neural network — typically a convolutional or transformer architecture trained on spoof-versus-bona-fide pairs — assigns each segment a score. Scores from all segments are pooled into one file-level probability. Some systems also return per-segment scores so you can see which stretch of a 40-minute interview triggered the alarm.
Stage 3 — Thresholding and the verdict
The probability is compared against a cutoff. Above it, the file is flagged synthetic; below it, human. That cutoff is a policy decision, not a scientific constant, and moving it trades false alarms against missed fakes.
Three stages, one brittle link: the model in stage two only recognizes patterns resembling what it saw in training. A voice engine released after the detector’s training cutoff is, to that detector, an unfamiliar accent it has never heard.
How accurate are AI voice detectors? What the benchmarks actually show
Lab numbers and field numbers diverge sharply, and the gap is the whole story. On the in-the-wild Deepfake-Eval-2024 benchmark, open-source audio deepfake detectors lost an average of 48% of their AUC compared with the academic datasets they were originally tested on, according to the Deepfake-Eval-2024 paper.
Commercial tools held up better. On the same in-the-wild benchmark, research summaries of Deepfake-Eval-2024 report that the best commercial audio deepfake detector reached 0.89 accuracy and 0.93 AUC, still short of human forensic analysts.
Here is what those metrics mean before you quote them in a meeting:
| Metric | What it measures | Why it misleads |
|---|---|---|
| Accuracy | Share of files labeled correctly | Inflated when the test set is mostly one class |
| AUC | Ranking quality across all thresholds | Says nothing about the threshold you actually ship |
| EER | Point where false accepts equal false rejects | Hides which error type hurts your workflow more |
| Per-model recall | Catch rate on one specific voice engine | Rarely reported for engines released this year |
A human baseline helps calibrate expectations. In a peer-reviewed PLOS ONE listening study, people correctly identified synthetic speech only 73% of the time, with no difference between English and Mandarin.
Read the vendor claim and the benchmark together. A detector advertising near-perfect results on a curated corpus is telling you about stage-two pattern matching under ideal conditions, not about the compressed TikTok rip your legal team forwarded.
Why accuracy collapses in the wild: compression, noise and unseen voice models
Real audio arrives damaged. It has been through a phone codec, a platform re-encode, a screen recording, maybe a translation and a loudness normalizer. Each pass strips the fine spectral detail detectors depend on.
The organizers of the ASVspoof 5 challenge, which drew submissions from 53 participating teams, report that detection performance degrades under adversarial attacks and neural encoding or compression. Neural codecs are now standard in conferencing and streaming. Your evidence file is almost never pristine.
Four failure conditions show up repeatedly:
- Codec damage. Low-bitrate encoding removes the high-frequency artifacts many classifiers key on.
- Background noise. Room tone, music beds and crowd noise blur the boundary between real and generated.
- Unseen generators. A model trained on last year’s TTS systems has no template for a release it never heard.
- Short clips. A three-second voice note gives the pooling layer almost nothing to average.
Post-processing also cuts the other way. Heavy denoising, de-essing and mastering on a genuine human recording can strip natural irregularity and push a real voice-over toward a synthetic-looking score.
AI voice detector vs. audio watermarking: proving origin instead of guessing it
Detection is forensic guesswork after the fact. Watermarking embeds an inaudible signal at the moment of generation, so verification becomes a lookup rather than an inference.
| AI voice detector | Audio watermarking | |
|---|---|---|
| When it acts | After the file exists | At generation time |
| What it produces | A probability | A present/absent signal with payload |
| Needs cooperation from the generator | No | Yes |
| Survives heavy re-encoding | Often poorly | Depends on the scheme’s robustness |
| Covers unknown third-party tools | Attempts to | No |
The two are complements, not rivals. Watermark everything your own pipeline generates so you can prove provenance for your own dubs; run a detector on inbound files you did not create, where no watermark will ever exist.
An absent watermark proves nothing. It means the file came from an unwatermarked tool, an older version, or a human — three very different conclusions that a missing signal cannot separate for you.
Where localization and content teams use AI voice detectors today
Four workflows justify the tooling for a content or localization team. Vendor QA comes first: when a dubbing subcontractor bills for human voice talent, a detector pass on delivered stems gives you a reason to ask a follow-up question.
Rights and consent checks come second. If a client supplies reference audio of a spokesperson for cloning, you want some signal about whether that reference is itself synthetic before it enters your training set.
Fraud screening is the third case, and it carries regulatory weight. The US Federal Communications Commission announced on 02/08/24 that calls using AI-generated voices are illegal under the Telephone Consumer Protection Act, which matters if your company runs outbound voice campaigns in the United States.
Platform compliance is the fourth. Several distribution platforms now require synthetic-media disclosure at upload, so a detector pass on third-party footage helps you fill that field honestly rather than guessing.
Rules differ by jurisdiction and by who is covered — the FCC action concerns calls under US telecom law, not video uploads, and EU and state-level obligations follow their own definitions. This is general information, not legal advice; check with counsel for your markets.
Reading a detector score responsibly: thresholds, EER and false accusations
A score of 0.82 is not "82% fake." It is the model’s confidence under its training distribution, and it shifts when the audio is compressed or the speaker’s language is underrepresented in that training data.
Set your threshold by consequence. For triage — deciding which of 300 submitted files a human reviews — tolerate false alarms and set the cutoff low. For anything that touches someone’s employment, contract or reputation, a detector output should never be the deciding evidence.
Humans are no safety net either. In that same PLOS ONE study, overall human accuracy was 70.35%, and listeners were worse at confirming genuine audio (67.78% correct) than at flagging fakes (73.0%).
Three rules keep you out of trouble:
- Never publish an accusation based on one detector run.
- Run at least two independent detectors and record disagreement as a result, not an error.
- Keep the original file, the codec chain and the score with its model version in your audit log.
Ask the supplier for raw sessions, project files or recording-day metadata before you escalate. Provenance evidence beats a probability every time.
Checklist: how to evaluate an AI voice detector before you trust it
Run these eight questions past any vendor:
- Which benchmarks, and in-the-wild or academic? Lab-only results tell you little about forwarded files.
- What is the EER, and at what threshold does the product ship? A headline AUC without an operating point is marketing.
- Which languages were in training? Performance on Tagalog or Vietnamese is not implied by English results.
- How recent is the training data? Ask for the cutoff date and the retraining cadence in months.
- Does it report per-segment scores? Segment-level output lets you find the spliced sentence inside a clean interview.
- How does it behave on compressed input? Request results on the codecs your files actually pass through.
- What happens to uploaded audio? Retention, region and deletion terms matter when the file is a client’s unreleased asset.
- Is there an API with versioning? You need to reproduce a six-month-old verdict with the same model build.
Test with your own material before signing. Build a small set of known-human recordings from your talent roster and known-synthetic files from the engines you use, degrade both through your real delivery chain, and compare the labels against ground truth you control.
Frequently asked questions
How accurate are AI voice detectors in real-world conditions?
Field accuracy is well below lab accuracy. On the in-the-wild Deepfake-Eval-2024 benchmark, the best commercial audio deepfake detector reached 0.89 accuracy and 0.93 AUC, while open-source audio detectors lost an average of 48% of their AUC compared with the academic datasets they were originally tested on.
Can an AI voice detector tell which tool generated the voice?
Most detectors only output a human-versus-synthetic probability, not an engine name. Some research systems attempt source attribution, but generators released after a model’s training cutoff fall outside its known classes, so attribution claims deserve more skepticism than detection scores.
Are humans better than software at spotting cloned speech?
No. In a peer-reviewed PLOS ONE listening study, people correctly identified synthetic speech only 73% of the time, with no difference between English and Mandarin, and overall human accuracy was 70.35% across both genuine and fake clips.
Why does compressed audio break detection?
Codecs discard the fine spectral detail many classifiers rely on. The organizers of ASVspoof 5, which drew submissions from 53 participating teams, report that detection performance degrades under adversarial attacks and neural encoding or compression — exactly what platform re-encoding applies to your files.
Is it legal to use AI-generated voices in customer calls?
It depends on jurisdiction and call type. The US Federal Communications Commission announced on 02/08/24 that calls using AI-generated voices are illegal under the Telephone Consumer Protection Act; other regions set their own rules. This is general information, not legal advice.
Sources
- Deepfake-Eval-2024: A Multi-Modal In-the-Wild Benchmark of Deepfakes Circulated in 2024
- Deepfake-Eval-2024 Benchmark (research summary)
- ASVspoof 5: Evaluation of Spoofing, Deepfake, and Adversarial Attack Detection Using Crowdsourced Speech
- Warning: Humans cannot reliably detect speech deepfakes (PLOS ONE)
- FCC — Consumer Policy Division
This article was drafted with AI assistance and published by the Dubbing AI Editorial Team after its facts were checked against the sources listed above.